For the last few weeks I’ve used a coding agent to find and fix backend performance issues in Sentry, starting from the traces Sentry sends to itself.
Most of the fixes only changed a line or two. But together, they removed hundreds of millions of queries a week, and some expensive lookups became hundreds or thousands of times faster (more details on that below).
Pointing the agent at our traces
I connected my agent (in this case Claude with Opus 5.5) to the Sentry MCP, pointed it at our own Sentry org and project, and asked it to find hot code path issues similar to a small performance PR I had drafted:
use the sentry mcp to look for more similar quick wins around hot path issues things
With the latest few model releases, I’ve found that you don’t have to be as specific with how you structure prompts, or make sure that you’re controlling context for the agent (for example sharing specific example spans). You can start with something as general as:
Find all the critical paths in my application. Use the sentry MCP to find their traces and find ways to optimize them.
Based on my initial prompt, the agent sorted spans by how often they ran and how long they took. For each candidate it gave me a file and line, an estimated weekly volume, and a link to an example trace. When the list got thin, I’d point it somewhere new. My prompts were short and mostly questions like:
“look for database heavy issues”
“is this change risky in any way?”
“did you validate the new query using EXPLAIN like we did earlier”
“rpc might also be interesting”
“i think there’s a pr from someone that might already fix this”
“lets not touch that area”
Then I’d pick an issue and have it investigate further before changing anything. It read the code and the git history and told me what might break. If the fix held up, it opened a draft PR.
Sentry is a large codebase, and there are areas I don’t know well enough to change confidently. I’d steer the agent away from those, check for work already in progress, and keep looking for something smaller. Making sure the agent has the ability to validate changes in the read-only database rather than guessing leads to much better results.
Django SDK instrumentation as a starting point
A lot of the Sentry codebase is in Django, and the Sentry Django SDK’s automatic instrumentation gave us a good starting point:
Django query spans include the SQL as their description. Our traces also include cache calls, cross-silo RPCs, tasks, and API routes. Grouping spans by description gave the agent a way to turn trace data into a ranked list of expensive work.
When query-source attributes were available on a database span, they gave the agent the file and line that ran the query.
The user_agent attribute showed that one busy endpoint was mostly sentry-cli set-commits --auto paging through an org’s repositories on every build. One org had ~16k repositories and was doing this roughly every 40 seconds. That led to a CLI change to avoid the pagination and a server-side index to make the queries cheaper for existing CLI versions.
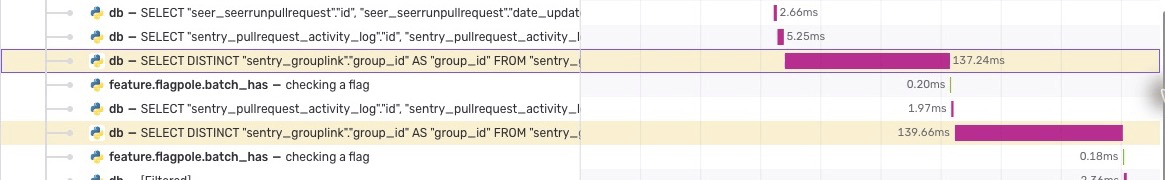
Every PR links an example trace showing the extra query or call, so that it’s a bit easier for a reviewer to understand. In one trace, a webhook ran the same 140ms query twice.
The result from removing a query was easy to see in a trace. To find out how much it mattered, I also checked request latency and database load in Sentry.
Checking query changes
For SQL changes, the agent ran EXPLAIN ANALYZE before and after on a read-only database mirror and compared the results. The clearest query cleanup was GroupHistory lookup (GroupHistory records each status change on an issue). The query asked for the newest row across several statuses, meaning Postgres read and sorted every matching row:
-- beforeSELECT * FROM sentry_grouphistoryWHERE group_id = %s AND status IN (1, 2, 11, 12, 13)ORDER BY date_added DESC LIMIT 1-- after: one probe per status, take the max in Python(SELECT date_added FROM sentry_grouphistory WHERE group_id = %s AND status = 1 ORDER BY date_added DESC LIMIT 1)UNION ALL ...
For the busiest group on the mirror this went from 935ms to 0.4ms with a warm cache.
Rearrange the GroupHistory query to use the existing index more efficiently when updating issue status. That query accounted for ~8% of disk reads on the primary database in our EU (Germany) region and ~3% in our US region, and its disk reads fell to nearly zero. Status changes in the occurrence consumer were ~30% faster in the US region and ~13% faster in the EU region versus the same time the previous day.
Add a missing table index for repository pagination. The paginated query alone accounted for ~1.6% of query execution time on the primary database in our US region before rollout. Average database execution fell ~69% (30ms → 9.2ms), with ~52% fewer cached block accesses per query. Requests weren’t consistently faster, but they did less database work.
Note: Query volumes and daily savings are estimates based on sampled spans and observed traffic. I compared database work per request or query so changes in traffic wouldn’t be misrepresented as performance improvements.
Prompt your agent to find performance issues in your app. You can start generally and work down to specific areas like:
“Find transactions where the same query, with different parameters, runs more than 10 times in a single trace (N+1).”
“Find SELECT * or wide queries on hot paths where only a few columns are used.”
“Find slow queries with ORDER BY ... LIMIT, OFFSET pagination, or LIKE '%...' that likely aren’t using an index.”
Pick an issue and have it investigate further before changing anything. Have it read the code and the git history and assess what might break. Then open a PR.
You can also use natural language queries in the Sentry UI’s Explore tabs for Logs, Traces, and Metrics to ask things like “Which database queries had the highest P95 duration over the last 7 days?”
Starting with Sentry Android SDK 8.51.0, profiling on Android 15+ devices is powered by Perfetto through Android's ProfilingManager API, with no configuration changes needed.
Most of a session happens after the page users landed on. With soft navigation web vitals in SDK v11, every page they visit gets its own LCP, CLS, and INP.
Two people and one beagle-shaped AI agent run madewithvuejs.com. Here's how Milly connects to GitHub, Linear, and Sentry to ship code and fix production bugs on her own.